Microsoft Global Outage Disrupts Teams and Outlook
When the digital channels went dark on Thursday, corporate conference rooms went silent with them. A sudden, widespread Microsoft global outage crippled essential office communication, knocking out access to Outlook, Teams, and specialized generative utilities for tens of thousands of professionals across multiple continents. The disruption laid bare the precarious single-point-of-failure vulnerabilities that govern modern business communication systems.
A severe Microsoft global outage disrupted core productivity tools, including Outlook, Teams, and Copilot, for tens of thousands of users worldwide. Caused by unexpected server unavailability that strained backup infrastructure, the incident cascaded across enterprise ecosystems, delaying financial earnings and impacting third-party AI platforms like OpenAI.<\/p>
- Widespread Operational Impact: Tens of thousands of global users experienced severe connectivity failures across Outlook, Teams, OneDrive, and Copilot.
- Ecosystem Contagion: Third-party AI platforms including OpenAI and Anthropic suffered performance degradation due to shared infrastructure dependencies.
- Root Cause Identified: Server nodes unexpectedly went offline, causing a traffic feedback loop that overwhelmed secondary cluster capacity.
- Corporate Fallout: Publicly traded organizations were forced to delay regulatory filings and financial earnings announcements due to data access losses.
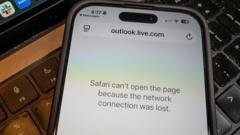
Reports of failing access flooded status tracking networks shortly before 18:00 GMT. Users from Tokyo to Singapore and across the United States found themselves logged out, unable to render calendars, or facing endless timeout screens on basic productivity applications. The event served as a stark reminder of how deeply reliant global business infrastructure has become on a tiny handful of centralized tech providers.
Understanding the Scope of the Microsoft Global Outage
The scale of the service drop materialized rapidly on network tracking sites. Downdetector logged a surge of user incident reports topping out near 140,000 within hours of the initial fault. While messaging and audio streaming in Microsoft Teams maintained partial functionality for some regional hubs, underlying directory services, file access, and calendar sync features froze entirely.
Corporate IT departments scrambled to diagnose what initially appeared to be internal network failures. However, public updates from software engineers at Microsoft quickly confirmed that the problem sat deep within their core data architecture. The company issued a statement noting that staff were aggressively pursuing multiple technical routes to mitigate user impact while working to stabilize core services.
“When an entire business software suite falters simultaneously, it isn’t just an IT nuisance; it is a full-stop interruption of modern commercial trade.”
Crucially, security analysts confirmed early in the event that there was no indication of malicious intent or external cyber-attack. Instead, the incident stemmed from internal system architecture friction, raising fresh questions about redundant load balancing within hyper-scale server operations.
The Anatomy of a Systemic Failure
Engineers tracing the technical failure identified a sudden drop in available processing nodes. According to preliminary updates released by the software provider, several server banks dropped offline without warning. That sudden deficit triggered an automated traffic redirection, forcing remaining servers to process an unsustainable volume of concurrent requests.
This sudden load transfer created an aggressive network bottleneck. Systems tasked with handling user authentication and token verification became bogged down. As secondary systems buckled under the surge, even services that had brief periods of stability dropped back offline. The resulting instability created a rubber-band effect where recovered networks quickly became unresponsive again under re-initiated connection traffic.
The issue impacted the broader Microsoft 365 disruption vector, hitting localized enterprise tenant accounts hard. Users attempting to access cloud storage through OneDrive reported synchronization loops, while users trying to invoke the Copilot AI platform were met with failed execution errors. The inter-dependency of these modern office tools meant that a failure in core authentication cascaded straight down to end-user applications.
Collateral Damage Across the Artificial Intelligence Landscape
The ripple effect extended far beyond traditional office productivity programs. Because hyper-scale computing relies on shared underlying resources, independent artificial intelligence developers found themselves caught in the wake of the server degradation. Strategic partners and competitors alike suffered collateral system friction.
Leading AI research studio OpenAI confirmed it was investigating connection anomalies that degraded tool functionality. Because large language models rely on complex infrastructure connections to handle high data throughput, backend server stutters can immediately disrupt user access. Similarly, reports pointed to degraded responses across other advanced AI providers, including Anthropic, highlighting how tightly knit the modern machine learning ecosystem is to foundational enterprise cloud backbones.
According to Reuters reporting on enterprise infrastructure vulnerabilities, centralized cloud arrangements can inadvertently turn minor hardware glitches into widespread commercial gridlock. When major processing nodes drop off the grid, the digital economy experiences immediate friction.
| Affected Platform | Primary Malfunction Observed | Operational Impact Level |
|---|---|---|
| Microsoft Outlook | Calendar sync failure, email retrieval timeouts | Critical |
| Microsoft Teams | Directory lookups frozen, file-sharing offline | High |
| Microsoft Copilot | API request dropouts, generation timeouts | High |
| OpenAI ChatGPT | Intermittent connection errors via backend hooks | Moderate |
| OneDrive | Cloud storage synchronization loops | Moderate |
Corporate Balance Sheets Feel the Strain
The operational freeze resulted in real financial friction. The disruption proved that cloud downtime carries tangible costs, affecting regulatory schedules and investor communications. Enterprise accounting departments were unable to access financial documentation stored within cloud repositories during critical quarter-end processing windows.
In one high-profile example, commercial electric vehicle maker Workhorse Group announced it was forced to push back its third-quarter earnings report. Originally scheduled to report quarterly metrics on November 12, the firm had to postpone its presentation to November 16, pointing directly to operational delays caused by the unexpected platform blackout.
Industry analysts at Bloomberg enterprise analysis have repeatedly pointed out that single-tenant reliance creates operational exposure for publicly traded entities. When data access drops for hours at a time, compliance officers cannot verify balance sheets or sign off on required financial filings on deadline.
Pattern of Fragility: A Recurring Infrastructure Challenge
This latest failure does not exist in a vacuum. It follows closely on the heels of another major cloud infrastructure failure last month, when an Azure server crash disrupted online tools for hundreds of enterprise clients worldwide. The short interval between these global incidents has reignited debates among software architects regarding the resilience of modern corporate cloud strategies.
Over the last decade, business leaders were encouraged to abandon on-premise hardware in favor of public cloud services. The promise was near-perfect uptime, lower maintenance expenses, and automatic software redundancy. Yet, as recent events demonstrate, migrating workload capacity to centralized environments simply trades local hardware risk for massive systemic exposure.
The Technical Realities of Server Cascade Failures
When enterprise systems fail at this scale, the primary technical culprit is almost always resource contention. Modern cloud networks use sophisticated load balancers to route traffic to available compute resources. If a foundational tier of server instances suddenly goes dark, the automated load balancers must re-route active user sessions to healthy clusters.
If those healthy clusters are already operating near peak efficiency, the incoming overflow traffic pushes CPU and memory utilization past safe thresholds. The newly overloaded servers then crash or begin dropping packets to protect their hardware, causing load balancers to dump even more traffic onto an ever-shrinking pool of functional machines. Recovering from such a failure cascade requires engineers to throttle incoming traffic, isolate healthy nodes, and slowly ramp capacity back up under controlled conditions.
Rethinking Enterprise Redundancy
In the wake of this latest platform instability, corporate technology officers are re-evaluating their enterprise stack risk. Relying on a single technology giant for email, video conferencing, document storage, and artificial intelligence tools creates an operational vulnerability that can paralyze a company’s workforce in an instant.
- Multi-Cloud Diversification: Enterprise clients are increasingly exploring hybrid deployment models, splitting business services across separate infrastructure providers to prevent complete corporate blackouts.
- Local Data Caching: IT departments are re-evaluating policies that push all file storage to remote systems, re-introducing cached local storage for mission-critical operations.
- Out-of-Band Communications: Organizations are establishing fallback communication systems completely independent of primary productivity suites to maintain internal coordination during server outages.
As service engineers work to fully stabilize backend nodes, corporate decision-makers are left reckoning with a clear operational truth. Modern enterprise productivity tools offer unmatched integration and efficiency when operating smoothly, but when the underlying cloud network buckles, the business world learns just how fragile digital infrastructure can be.
<button type="button" onclick="this.parentElement.innerHTML='✓ Thank you, we will refine our analysis!‘” style=”background:#ffffff; border:1px solid #cbd5e1; border-radius:6px; padding:4px 12px; font-size:12px; cursor:pointer; color:#334155;”>👎 No
Latest Analytical Follow-up: For continuous developments on this subject, read our full investigation on AI Housefishing: When Property Listings Distort Reality.
Latest Analytical Follow-up: For continuous developments on this subject, read our full investigation on Microsoft 365 Outage Exposes Global Reliance on Tech Giants.
